ScrapingBee logo
  • Pricing
  • Documentation
  • Product
    • HTML API FeaturesCore AI Data ExtractionExtract structured data via AI Markdown ScraperGet any page as clean Markdown ScreenshotsCapture full-page screenshots via API JavaScript ScenarioClick, scroll and type before scraping CSS/XPath Data ExtractionTarget exact elements with selectors
    • Developer tools and integrations CLIScrape straight from your terminal MCP ServerConnect AI assistants to ScrapingBee n8nAutomate scraping in n8n workflows MakeAdd scraping to Make scenarios Claude CodeUse ScrapingBee inside Claude Code CodexUse ScrapingBee inside Codex CursorScrape without leaving Cursor View all integrations
    • Dedicated Scraper APIs Google APIFetch search results into JSON Employee Search APITurn prompts into employee data Fast Search APIFetch sub-second web search results ChatGPT APICollect structured ChatGPT responses Gemini APIQuery Gemini for RAG-ready citations Amazon APIScrape product details and reviews Walmart APIPull store inventory and pricing data YouTube APIGrab video data and transcripts View all
  • FAQ
  • Blog
  • Resources
    • Tutorials
    • Knowledge Base
  • Login
  • Sign Up

The ScrapingBee Blog

We help you get better at web-scraping: detailed tutorials, case studies and writings by industry experts.

Don't know where to begin?

Check out our most popular articles.

Web scraping without getting blocked Web scraping without getting blocked Web scraping in Python Web scraping in Python Web scraping in NodeJS Web scraping in NodeJS Web scraping in R Web scraping in R Web scraping in C++ Web scraping in C++ Web scraping in C# Web scraping in C# Web scraping in Php Web scraping in Php Web scraping in Scala Web scraping in Scala Java web scraping Book Java web scraping Book Web scraping in Ruby Web scraping in Ruby Web scraping in Go Web scraping in Go Web scraping in Elixir Web scraping in Elixir Web scraping in Rust Web scraping in Rust Web scraping in Perl Web scraping in Perl No code web scraping No code web scraping No code competitor monitoring No code competitor monitoring
Web Scraping with Groovy blog post cover
20 min read

Web Scraping with Groovy

This article discusses how to use Groovy and Jodd HTTP to extract information from the web. It covers topics from how to compile a basic HTTP request to setting up a full-fledged headless browser environment with Selenium in Groovy.

Photo of Alexander M
Alexander M 16 January 2026
What is data parsing? blog post cover
10 min read

What is data parsing?

Data parsing is the process of taking data in one format and transforming it to another format. This is particulary interesting for web scraping.

Photo of Kevin Sahin
Kevin Sahin 16 January 2026
'JMAP (YC S10) Linux Inside is hiring': the quest for the best Hacker News title  blog post cover
5 min read

'JMAP (YC S10) Linux Inside is hiring': the quest for the best Hacker News title

Analysing 2.8 millions Hacker News posts titles in order to generate the one that would perform the best, statistically speaking.

Photo of Pierre de Wulf
Pierre de Wulf 15 January 2026
10 Tips on How to make Python's Beautiful Soup faster when scraping blog post cover
19 min read

10 Tips on How to make Python's Beautiful Soup faster when scraping

Learn how to speed up BeautifulSoup for web scraping with these essential tips. Optimize parser choice, CSS selectors, concurrency, and profiling with cProfile analysis.

Photo of Satyam Tripathi
Satyam Tripathi 15 January 2026
Create a sitemap link extractor using ScrapingBee in N8N blog post cover
9 min read

Create a sitemap link extractor using ScrapingBee in N8N

An easy way to get all relevant links of a website is by fetching links from its sitemap. In this blog post we will create an n8n workflow that uses scrapingbee to extract links from sitemap.

Photo of ScrapingBee Team
ScrapingBee Team 15 January 2026
Free AI Powered Proxy Scraper for Getting Fresh Public Proxies blog post cover
8 min read

Free AI Powered Proxy Scraper for Getting Fresh Public Proxies

Discover how to scrape fresh public proxies with a free AI-powered tool! Learn Python scripts, test proxies, and boost your scraping efficiency with ease.

Photo of Karthik Devan
Karthik Devan 15 January 2026
How to Build a Fast Scraping Bot: 2x Speed with Python Threading blog post cover
15 min read

How to Build a Fast Scraping Bot: 2x Speed with Python Threading

Learn how to effectively use scraping bots for web data extraction. Discover practical tips and techniques to master your data-gathering skills. Read more!

Photo of Kevin Sahin
Kevin Sahin 15 January 2026
How To Set Up A Rotating Proxy in Selenium with Python blog post cover
10 min read

How To Set Up A Rotating Proxy in Selenium with Python

Ready to enhance your Selenium web scraping? Set up rotating proxies with our easy-to-follow Python tutorial and take your projects to the next level.

Photo of Satyam Tripathi
Satyam Tripathi 15 January 2026
Ruby HTML and XML Parsers blog post cover
7 min read

Ruby HTML and XML Parsers

Web scraping comes in handy when collecting large amounts of data from the internet. This roundup shares a list of popular Ruby HTML and XML parsers that you can use to simplify web scraping.

Photo of Tahanima Chowdhury
Tahanima Chowdhury 15 January 2026
Study of Amazon’s Best Selling & Most Read Book Charts Since 2017 blog post cover
31 min read

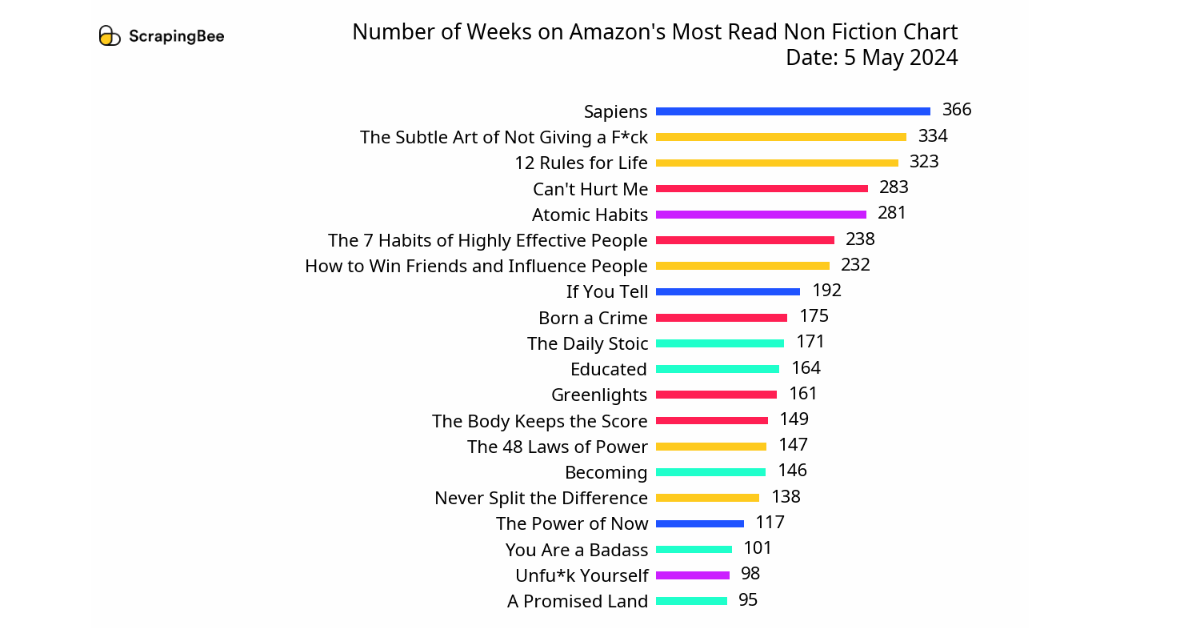
Study of Amazon’s Best Selling & Most Read Book Charts Since 2017

Discover the most popular books on Amazon! (since 2017) Our in-depth analysis reveals the top-selling and most-read titles, scraped directly from Amazon data.

Photo of Karthik Devan
Karthik Devan 15 January 2026
Previous
  • 1
  • 2
  • 3
  • 4
  • 5
  • 6
  • 7
  • 8
  • 9
  • 10
  • 11
  • 12
  • 13
  • 14
  • 15
  • 16
  • 17
  • 18
  • 19
  • 20
  • 21
  • 22
  • 23
  • 24
  • 25
  • 26
  • 27
  • 28
  • 29
  • 30
  • 31
  • 32
  • 33
  • 34
  • 35
  • 36
  • 37
  • 38
  • 39
  • 40
Next

Tired of getting blocked while scraping the web?

ScrapingBee API handles headless browsers and rotates proxies for you.

Get access to 1,000 free API credits, no credit card required!

Try ScrapingBee for Free
ScrapingBee

ScrapingBee API handles headless browsers and rotates proxies for you.

Company

  • Blog
  • Rebranding
  • Affiliate Program

Tools

  • Curl converter

Legal

  • Terms of Service
  • Privacy Policy
  • GDPR Compliance
  • Data Processing Agreement
  • Cookie Policy
  • Acceptable Use Policy
  • Legal Notices

Product

  • Pricing
  • Status

How we compare

  • Alternative to Firecrawl
  • Alternative to Apify
  • Alternative to Tavily
  • Alternative to Exa

Scrapers

  • Amazon Scraper
  • ChatGPT Scraper
  • Walmart Scraper
  • Google API
  • HomeDepot Scraper
  • Costco Scraper
  • Expedia Scraper
  • Google Jobs Scraper
  • Google News Scraper
  • Google Play Scraper
  • All Scrapers

No code web scraping

  • No code web scraping
  • No code competitor monitoring
Learning Web Scraping

  • Web scraping questions
  • A guide to Web Scraping without getting blocked
  • Web Scraping Tools
  • Best Free Proxies
  • Best Mobile proxies
  • Web Scraping vs Web Crawling
  • Rotating and residential proxies
  • Web Scraping with Python
  • Web Scraping with PHP
  • Web Scraping with Java
  • Web Scraping with Ruby
  • Web Scraping with NodeJS
  • Web Scraping with R
  • Web Scraping with C#
  • Web Scraping with C++
  • Web Scraping with Elixir
  • Web Scraping with Perl
  • Web Scraping with Rust
  • Web Scraping with Go

Copyright © 2026

Made in France