Jev is a new kind of AI model developed by TypeSafe and launched in September 2026. It has been deployed for a variety of use cases that were typically handled by LLMs. However, it differs from an LLM because it cannot generate any free-form text at all. It only gives structured outputs and enables decision-making in an automated pipeline.
In this guide, we break down what Jev is and how it can be used in a scraping pipeline (with examples). We also look at the costs involved and discuss when to use Jev versus an LLM or CSS selectors.
Can You Use Jev for Web Scraping?
Jev is a "System One" AI model that can be used in specific parts of a web scraping workflow where decision-making based on natural language text or HTML code is necessary. It can take an input, some questions about the input, and return structured probabilistic outputs. Jev cannot generate any kind of free-form text or media, so it is not a cheap LLM replacement. Jev also cannot access webpages or bypass anti-bot protections on its own, so it needs to be paired with a library such as requests or an API such as ScrapingBee to get content off the internet.
What Jev is (and isn’t)
Jev is an AI model that falls under the category of "System One" models. It can take free-form inputs such as text and images, but it generates only structured, probabilistic outputs. The outputs can be of four types: choice, score, noul, and box, in response to specific questions about the inputs.
The choice type picks a single option from a given list, and the score type rates an input across ordered levels. The noul type simply returns a yes/no with a probability score. The box type is used specifically for asking where something is within an image, and it returns 4 values corresponding to the left, right, top, and bottom positions.
Jev was created by TypeSafe AI and launched in September 2026. Since it does not work like traditional LLMs, the company is able to offer it at a significantly lower cost of USD 0.042 per million input tokens. Output tokens are free. Common use cases include classifying support tickets and flagging spam. One could also redo our mapping of the funniest US states on Reddit more efficiently using Jev instead of a traditional LLM.
While Jev can do all of this, it can't generate arbitrary text. So it cannot be a cheap replacement for ChatGPT or Claude. It is simply not an LLM. Even in a structured format it cannot generate any strings. With choice, score, or noul output types, it simply picks one value from multiple predefined string-typed choices, numerical ranges, or booleans (yes/no) with a probability. So it will not work out of the box for converting a free-form text into a structured format by extracting certain information. Jev is a model that replaces LLMs for specific use cases, and it's able to offer significant cost savings by doing so.
What Jev can do in a scraping pipeline
Jev can be used in a scraping pipeline for a variety of decision-making steps, such as classification, scoring, and if-else workflows. Here are some examples:
- If/else: Scrape a page without JS-rendering, ask Jev if it has the expected content, and switch to JS-rendering only if the expected content hasn’t loaded.
- Classification: Scrape a product review and get its focus; it could be quality, price, shipping, or support.
- Scoring: Scrape a news article mentioning a specific brand and score how positively it talks about the brand.
What Jev can’t do
While using Jev, it is also important to understand what Jev cannot do in a scraping pipeline:
- Jev cannot extract arbitrary strings from a web page. It can only return a choice, score, noul, or a box. To extract arbitrary strings in a structured format from the web page content, you can use ScrapingBee's AI Data Extraction
- Jev cannot browse or fetch pages. It can only take an input text/image and give you a structured probabilistic output. You have to set up the fetching and processing to supply inputs to Jev.
- Jev cannot answer open-ended questions such as "Summarize this article" or "What are the common customer complaints in the reviews section?" It can only give specific answers based on only the input material and choice/score/noul questions.
Setup
To get started with Jev, you first need to set up an account on typesafe.ai to use their API. They provide SDKs for Python and JavaScript/TypeScript. Alternatively, you can use Jev via a third-party interface such as OpenRouter if you already have an account and billing setup there. In this blog, we'll use Python for the setup and tutorials.
NOTE: All the code samples assume you have set your TypeSafe API Key as the TYPESAFE_API_KEY environment variable and your ScrapingBee API Key as the SCRAPINGBEE_API_KEY environment variable.
You can install the TypeSafe Python SDK using the package name typesafe-sdk. The tutorials below also use the ScrapingBee SDK, which you can install using the package name scrapingbee. You can install both as follows:
uv add typesafe-sdk scrapingbee
or
pip install typesafe-sdk scrapingbee
Once you've installed the packages, try out a basic example to get a feel for how the TypeSafe SDK works:
from typesafe_sdk import Choice, TypeSafeClient

input_content = "What is the color of the sky during daytime on a sunny day?"

with TypeSafeClient(model="jev-1.14.0") as client:
    # Uses TYPESAFE_API_KEY from environment
    response = client.system_one(
        state=input_content,
        questions={
            "color": Choice(
                instructions="Pick a color from the options",
                criteria={
                    # "value": "description"
                    "blue": "Blue color",
                    "green": "Green color",
                    "red": "Red color",
                    "white": "White color",
                    "black": "Black color"
                },
            )
        }
    )

    print(response.answers["color"].choice)
If the above program prints any of the color values under criteria, you're good to go. Most of the time it will print 'blue,' but there is a minor chance it could print some other color. This is because Jev is not deterministic; it is a probabilistic AI model. Sometimes, it might even make sense to run this multiple times to take the most common values for choice or an average value for a score across all the runs.
Tutorial 1: Classifying scraped job postings with Jev
Let's say you're trying to build a job scraper. Parsing and extracting structured data that is present in the job listing, such as job title, location, and description, can be done through CSS selectors or a regular LLM call, as we've shown in our blog about building a job aggregator. Next, you might want to process the job posting to derive some additional data, such as whether the job posting is remote. Or you might want to categorize it based on the description because no explicit category is mentioned. These are use cases that need the text to be processed by an AI model. While a regular LLM works out well, Jev is much cheaper and more efficient when the output you need is just a set of decisions. The example below shows processing a job description through Jev to extract a category, a workload pressure score, and whether the job is fully remote.
import os
import sys

from scrapingbee import ScrapingBeeClient
from typesafe_sdk import Choice, Noul, Score, TypeSafeClient

job_url = 'https://jobs.lever.co/honkforhelp/c488adf1-d17f-46c1-ac3f-cd799bf7f486'

# Initialize ScrapingBeeClient
client = ScrapingBeeClient(api_key=os.environ['SCRAPINGBEE_API_KEY'])

# Fetch the Job Posting from the URL
response = client.html_api(job_url,
    params = {
        'return_page_markdown': 'True',
        'render_js': 'True'
    }
)

print('Job Response HTTP Status Code:', response.status_code)

if response.status_code != 200:
    print("Failed to fetch job web page. Exiting")
    sys.exit(1)

job_posting_text = response.text

# define question to ask Jev about the job posting
questions = {
    "category": Choice(
        instructions="What is the role category",
        criteria={
            "Engineering": "Software development, DevOps, data engineering, QA",
            "Design": "Product, UX, UI, or graphic design",
            "Marketing": "Content, SEO, growth, brand, or communications",
            "Sales": "Sales, account management, or business development",
            "Other": "Any role that fits none of the above",
        },
    ),
    "workload_pressure": Score(
        instructions="How much does the posting signal a heavy workload or high-pressure environment",
        criteria=[
            "No signals of pressure, relaxed or balanced tone",
            "Mild signals, such as 'busy team' or 'deadlines'",
            "Clear signals, such as 'fast-paced' or 'wear many hats'",
            "Strong signals, such as 'work hard play hard', 'thrive under pressure', or on-call and long hours",
        ],
    ),
    "fully_remote": Noul(
        instructions="The posting states the role can be done fully remotely",
        criteria={
            "true": "Fully remote, work from anywhere, or remote with no office requirement",
            "false": "Onsite, hybrid, or remote status not stated",
        },
    ),
}

with TypeSafeClient(model="jev-1.13.0") as client:
    response = client.system_one(state=job_posting_text, questions=questions)

    # get category from choice
    category = response.answers["category"].choice
    category_probability = response.answers["category"].probabilities[category]

    # get pressure score
    pressure = response.answers["workload_pressure"].score

    # get remote noul as a probability, take True is noul > 0.75
    remote = response.answers["fully_remote"].noul > 0.75

    print("Job Category:", category, f'({category_probability})')
    print("Work Pressure Estimate (0-3):", pressure)
    print("Fully Remote:", remote, f'({response.answers["fully_remote"].noul})')
    print("Input Tokens Used:", response.usage.input_tokens
Running the above code gave us the following output:
Job Response HTTP Status Code: 200

Job Category: Engineering (0.65)

Work Pressure Estimate (0-3): 2.0

Fully Remote: True (0.98)

Input Tokens Used: 1700
So we were able to get structured answers to specific questions about the job posting from an AI model (along with probabilities as applicable). This is different from regular scraping, where you're only extracting the information already mentioned somewhere on the web page. These kinds of questions would typically need a human or an AI model to actually read the job posting to be answered. Finally, you can see that 1700 input tokens were used for this response.
Tutorial 2: Filtering scraped Google search results with Jev
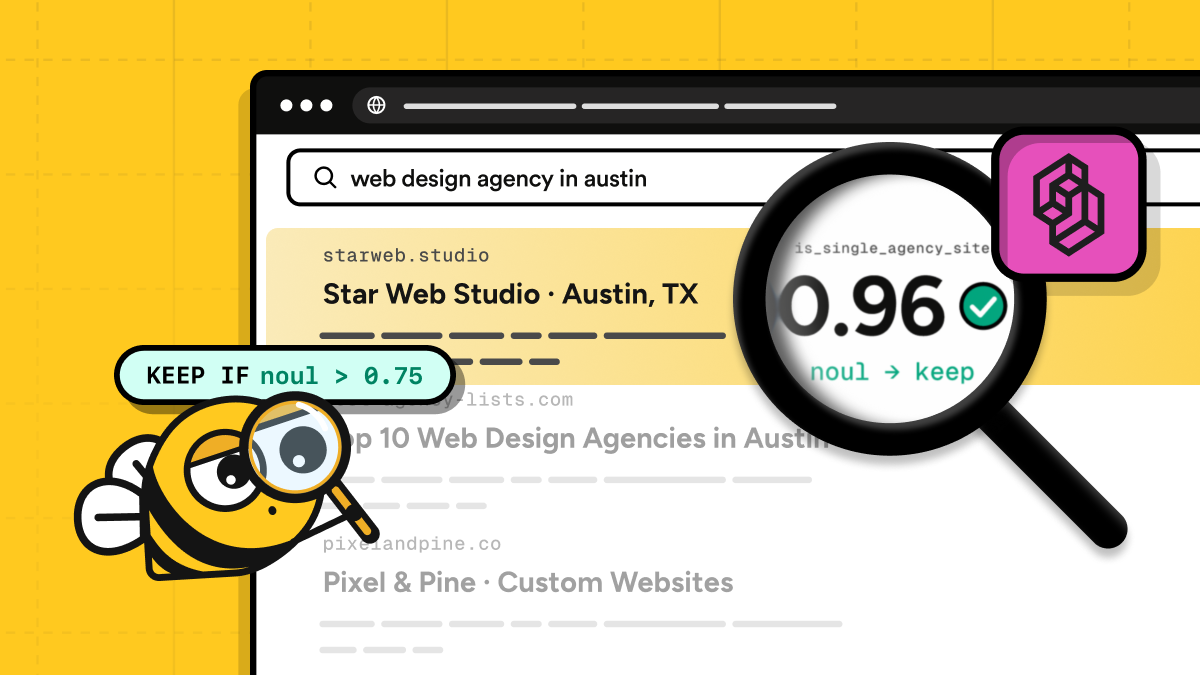
Jev can also be used to filter search results scraped from Google to find just the ones that are relevant to the intent. For example, assume you're looking for web design agencies in a specific city, say, Austin. Google search will return a mix of actual agency websites, along with aggregate pages from Yelp and listicles like "Top 5 Web Design Agencies in Austin." You only need the former, and Jev can help you automatically filter out just the results that link to single agency pages. The following Python program searches Google using the ScrapingBee Google API, filters with Jev, and shows you just single agency links from the results:
import os
import sys
from scrapingbee import ScrapingBeeClient
from typesafe_sdk import Noul, TypeSafeClient

# Initialize ScrapingBeeClient
client = ScrapingBeeClient(api_key=os.environ['SCRAPINGBEE_API_KEY'])

# Search Google with ScrapingBee Google API
response = client.google_search(
    search='Web design agency in Austin',
    params={
        'country_code': 'us',
    }
)

print('Search Response HTTP Status Code:', response.status_code)
if response.status_code != 200:
    print("Failed to fetch search results. Exiting")
    sys.exit(1)

results = response.json()['organic_results']

# Frame question for Jev
questions = {
    "is_single_agency_site": Noul(
        instructions="The result is the own website of a single agency",
        criteria={
            "true": "A company's own site selling its services",
            "false": "A directory, listicle, review site, or marketplace",
        },
    ),
}


with TypeSafeClient(model="jev-1.14.0") as client:
    jev_tokens_used = 0
    print("\nAgencies Found in Search:\n")

    # Iterate over results
    for result in results:
        state = f"{result['title']}\n{result['displayed_url']}\n{result.get('description') or ''}"

        # Run each result through Jev
        response = client.system_one(state=state, questions=questions)

        # Print result and probability of it being a single agency link
        noul_value = response.answers["is_single_agency_site"].noul
        print(result["displayed_url"], "-", result["title"])
        print("Single Agency Probability:", noul_value, "\n")

        # Keep track of tokens used
        jev_tokens_used += response.usage.input_tokens
    print("\nTotal Jev tokens used:", jev_tokens_used)
Running the above code gave us the following output (as of October 30, 2026):
Agencies Found in Search:

https://websitedesignaustintexas.com - Website Design Austin Texas: Complete Web Design Services
Single Agency Probability: 0.93

https://www.glidedesign.com - Austin Web Design, Development & SEO - Texas-based ...
Single Agency Probability: 0.95

https://www.yelp.com› Professional Services - Top 10 Best Web Design Near Austin, Texas (Updated 2026)
Single Agency Probability: 0.04

https://helmsworkshop.com - Helms Workshop | Branding & Design Agency Based in Austin ...
Single Agency Probability: 0.96

https://clutch.co› web-designers › austin - Austin Web Designers - Oct 2026 Rankings
Single Agency Probability: 0.04

https://austinwebanddesign.com - Austin Web Design Company • Custom WordPress Websites ...
Single Agency Probability: 0.95

https://www.geekpoweredstudios.com› custom-web-de... - Web Design Company in Austin
Single Agency Probability: 0.88

https://madebyevoke.com› Blog - Top 10 Web Design Agencies in Austin, Texas (2027) - Evoke
Single Agency Probability: 0.41

https://www.pallasweb.com - Austin Web Design & Development Company | PALLASART
Single Agency Probability: 0.94


Total Jev tokens used: 3338
Looking at the above results, you can see that single agency links have a high noul of 0.88 or above. Listicles and aggregators have a noul of 0.41 or less. You can now build a filter with a noul cutoff of 0.8 or so. Processing a page of search results used 3338 input tokens for Jev.
Cost breakdown
Jev costs USD 0.042 per million input tokens. The outputs are structured and short, and the token counts are negligible. As a result, TypeSafe offers Jev's output tokens for free. Let's look at how the cost works out for the two tutorials we demonstrated.
For processing a job posting, 1700 tokens were sent to Jev. Going by this, you can process about 14000 job listings for just 1 USD. Even if you ran each request thrice to take an average, you could still do more than 4000 job listings with 1 USD.
Next, for processing a page of search results, 3338 tokens were used, which cost approximately USD 0.00014. In other words, you can process around 7000 pages of search results for 1 USD.
The costs mentioned above are just Jev’s costs. Additionally, each request to the ScrapingBee API costs credits. For simple HTTP requests it costs 1 credit, and for JS rendering, each request costs 5 credits. You can see the credit costs for using various parameters in our documentation. In addition to this, if you run the scraper on the cloud, there could be costs for storage, bandwidth, etc.
Failure modes and pitfalls
Jev is not a traditional LLM, and when something is off, it may not tell you that something is off, unlike Claude or ChatGPT. It will still attempt to produce structured outputs to answer the questions you asked. For example, say you scrape a job listing URL, get a 404 page or CAPTCHA block, and then unknowingly run that through Jev to ask if it's remote. You will simply get "no" for an answer with a probability, not a response that says, "This is not a job listing; something is off."
Next, the outputs are better when the questions are to the point. If you're grading a resume with Jev, a vague question such as "How good is this candidate" may not give you usable scores. Instead, you might want to feed your job description along with the resume and ask specific questions like "Does the candidate mention relevant experience points suitable for the job?" or "Does the candidate's experience demonstrate the required skill sets?" Ideally, you'd want to have a bunch of specific questions like these and construct an aggregate score, taking a weighted sum of the answers Jev gives you.
Also, while using nouls, you get a probability that can range between 0 and 1. Depending on the specific question, you'd want to define an arbitrary cutoff for taking a value as true/false/ambiguous. It helps to manually inspect the probabilities after running a small sample set and defining a threshold based on that. This minimizes the chance for surprises when you scale to a larger set of documents.
Finally, try to avoid using jev-latest as the model in production. This is a dynamic pointer to the latest released model that changes every time a new version is released. The responses can vary with each version of the model, and it is helpful to pin one version to get roughly consistent outputs. There may still be some variation because Jev is not deterministic, but it's better to keep track of which version you're working with. For this reason, we used jev-1.14.0 as the model in our code. Even if you run this code a few months from now, you will get similar outputs.
When to use Jev vs. an LLM vs. CSS selectors
For scraping uses, Jev works best when you have questions about the scraped content that need probabilistic answers. These answers may not be embedded in the content itself but require a human or an AI model going through the content. LLMs, on the other hand, work best to summarize or generate any other content from the scraped content. They can also be used to extract structured data from scraped web pages, especially when HTML structure cannot be expected to stay constant. CSS selectors work best to extract data from a web page into a structured format when you know that the HTML structure will not change. It is more efficient but needs to be frequently monitored. If the HTML structure changes, your CSS selector-based scraper may break. This is summarized briefly in the table below:
| Method | Best For | Examples |
| Jev | Decision-making based on scraped content | Is the scraped product in stock? Is the article relevant to a criterion? Is the job remote? |
| LLM extraction | Structured data extraction from free-form text, summarization | Extract product specifications, job requirements, contact details, etc. from one or more websites |
| CSS Selectors | Structured data extraction from pages with uniform and stable HTML structures | Headlines, product titles, list of linked pages, table rows |
With our Google search scraping example, you could use CSS selectors to extract the title, description, URL, etc., when you have the HTML page. We used the ScrapingBee API, which does all of this on the backend and gives you ready-to-use results in JSON format. If you need specific entity names from the results, you can use LLM extraction. But if you need to decide if a particular result is relevant to a particular criterion, Jev works out best. You could use an LLM too, but Jev is cheaper and more efficient at the listed token prices.
Next Steps
Ready to get started with Jev? You can give it a go from the TypeSafe console or OpenRouter. To supply Jev with the scraped content that it needs to make decisions, you can use the ScrapingBee API. We have a free trial to get you started.
FAQ
What does Jev AI do?
Jev is an AI model developed by TypeSafe that generates typed probabilistic responses as a choice, score, noul, or box instead of natural language text or media. It is used for obtaining structured outputs for decision-making from text or image inputs.
What does Jev stand for?
Jev is not an acronym. The name refers to the Jevons Paradox, which states that when a resource becomes more efficient, its total consumption increases. This paradox is itself named after 19th-century English economist and logician William Stanley Jevons, who first described it in his book, The Coal Question.
Is Jev AI open source?
Jev AI is not open source or open weights. So it has to be used only through the cloud API of its developer TypeSafe. It is also available through select third-party AI gateways such as OpenRouter. It cannot be downloaded and run locally.
Can Jev be used for web scraping?
Jev can be used for specific parts of a web scraping workflow that involve decision-making. This could be classifying a page or a data point, filtering results, checking for error or CAPTCHA pages, deciding which links to follow, or ranking content as per specific criteria. By itself, it cannot access URLs, use proxies, or extract content from web pages.
Who built Jev AI?
Jev was built by a San Francisco-based startup called TypeSafe AI. It was founded in 2024 by Diogo Almeida, Erik Gafni, and Sasha Sheng. Diogo Almeida is a former OpenAI researcher who worked on ChatGPT and GPT-4.