
Apify alternative
ScrapingBee vs Apify
If you're looking for an Apify alternative, ScrapingBee offers a direct API-first approach to web scraping with managed proxies, browser rendering, and AI extraction.
 Sign up with Google
 based on 29 G2 reviews
(*) Concurrency figures are not directly equivalent: ScrapingBee limits concurrent API requests, while Apify limits concurrent Actor runs; request concurrency within an Actor depends on its implementation and configuration.
(**) Pricing is not directly comparable between the two platforms. ScrapingBee uses API credits, with credit consumption depending on features such as JavaScript rendering, premium proxies, AI extraction, and other options. Apify pricing is based on platform resource usage and may also vary by Actor and pricing model. Estimated costs are based on comparable basic scraping workloads, while actual costs depend on the configuration and features used.
Comparison based on publicly available pricing, documentation, and product information as of September 2026. Plan limits, features, pricing, and usage policies may change over time.
Mike Ritchie
CEO @ SeekWell
ScrapingBee simplified our day-to-day marketing and engineering operations a lot. We no longer have to worry about managing our own fleet of headless browsers, and we no longer have to spend days sourcing the right proxy provider
Trusted by web scraping teams
based on 29 G2 reviews
Built for
Why teams evaluate Apify alternatives
Compare Apify alternatives based on how your team builds, runs, and scales scraping workflows.
Apify is designed as a broad automation platform for scraping, storage, scheduling, proxies, and Actors. If your main goal is web scraping and extraction, a more focused API-first alternative may be easier to integrate into your existing workflow.
When evaluating alternatives to Apify, consider how much platform infrastructure your workflow actually needs.
Apify combines Actors, scheduling, storage, and marketplace tooling, while ScrapingBee gives teams a more focused way to handle web scraping, browser rendering, proxy management, and extraction through a standard HTTP API.
Common factors to consider
Direct scraping API vs Actor-based automation
Proxy management and geotargeting
JavaScript rendering and browser actions
AI and structured data extraction
Ready-made scrapers and target-specific APIs
Pricing and scaling requirements
Access and extract web data with a few lines of code
ScrapingBee is an Apify alternative for teams that want direct control over how they fetch pages and extract data. Start with a standard request, then add JavaScript rendering, proxy geotargeting, browser actions, or structured extraction as needed.
Request
# pip install requests beautifulsoup4
import json
import os

import requests
from bs4 import BeautifulSoup

response = requests.get(
    "https://app.scrapingbee.com/api/v1/",
    params={
        "url": "https://news.ycombinator.com/",
        "render_js": "false",
    },
    headers={
        "Authorization": f"Bearer {os.environ['SCRAPINGBEE_API_KEY']}",
    },
    timeout=60,
)

response.raise_for_status()

soup = BeautifulSoup(response.text, "html.parser")

stories = [
    {
        "title": link.get_text(strip=True),
        "url": link.get("href"),
    }
    for link in soup.select(".titleline > a")[:10]
]

print(json.dumps(stories, indent=2))
Response
[
  {
    "title": "Gpiozero Flow",
    "url": "https://bennuttall.com/blog/2026/07/gpiozero-flow/"
  },
  {
    "title": "Azulejo",
    "url": "https://en.wikipedia.org/wiki/Azulejo"
  },
  {
    "title": "AI's top startups are barely publishing their research",
    "url": "https://www.science.org/content/article/ai-s-top-startups-are-barely-publishing-their-research"
  },
  {
    "title": "Carolina Cloud pays SOFR on unused prepaid credits",
    "url": "https://docs.carolinacloud.io/organizations/prepaid-interest/"
  },
  {
    "title": "The coolest use for the Vision Pro",
    "url": "https://christianselig.com/2026/07/vision-pro-house/"
  }
]
Fetch a static Hacker News page without browser rendering, then parse the first ten story titles and links from the returned HTML
Input parameters
Target URL
The webpage you want ScrapingBee to retrieve.
Auto Mode
Let ScrapingBee automatically choose between JavaScript rendering, premium proxies, and stealth proxies, with an optional cap on the Auto Mode configuration cost.
JavaScript rendering
Enable or disable browser rendering for dynamic, JavaScript-heavy websites.
Proxy type
Use the default rotating proxy pool, or enable premium or stealth proxies for more difficult targets.
Proxy geotargeting
Send the request through a proxy in a selected country using a two-letter country code.
Data extraction
Extract structured data with CSS or XPath selectors, use a natural-language query, or define fields with AI extraction rules.
Browser actions
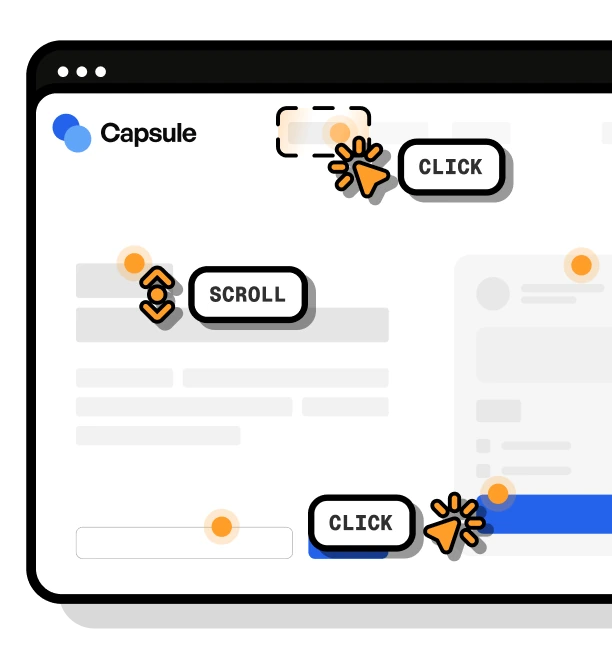
Click elements, fill forms, scroll, wait for content, or execute JavaScript before returning the response.
Everything else
Return page content as Markdown or text, capture screenshots, select a device, forward custom headers, wait for specific elements, manage sessions, and configure other request options.
Full HTML API DocumentationTest ScrapingBee with
your own scraping workflow
Get 1,000 free API credits to try browser rendering, managed proxies, geotargeting, extraction, and other ScrapingBee features. No credit card required.
How it works
How to start scraping
with ScrapingBee
Use ScrapingBee as an Apify alternative by sending your target URL directly to the API, choosing how you want to fetch the page and extract the data, and scaling without managing proxies or browser infrastructure yourself.
Create your account
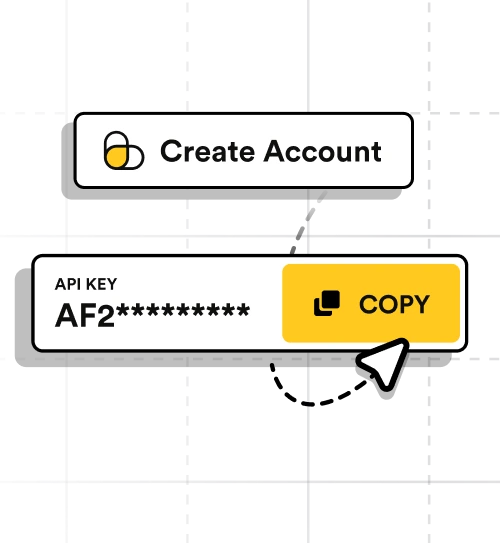
Get instant access to your API key and 1,000 free credits. No credit card is required.
Send your first request
Call ScrapingBee from any language or tool that can send HTTP requests, test requests in the dashboard, or connect the API to tools such as Make and n8n. ScrapingBee handles proxy rotation, browser rendering, and retries for you.
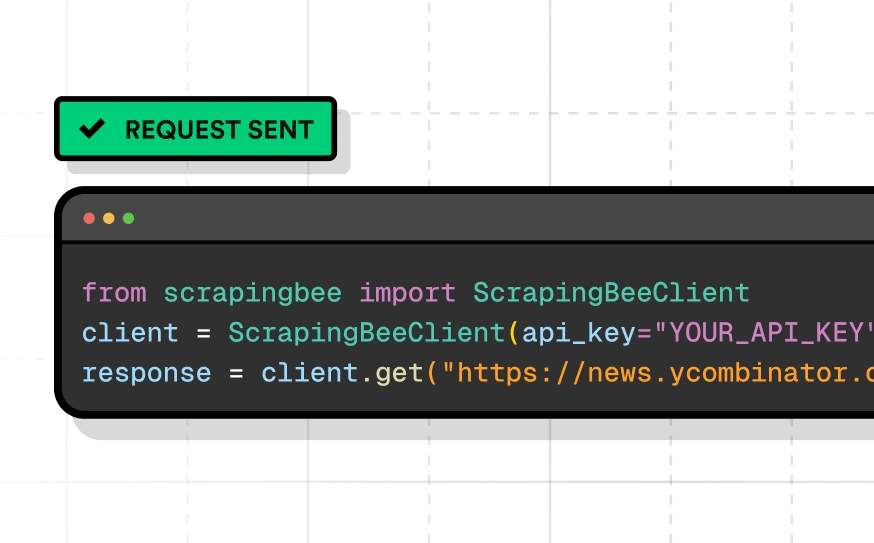
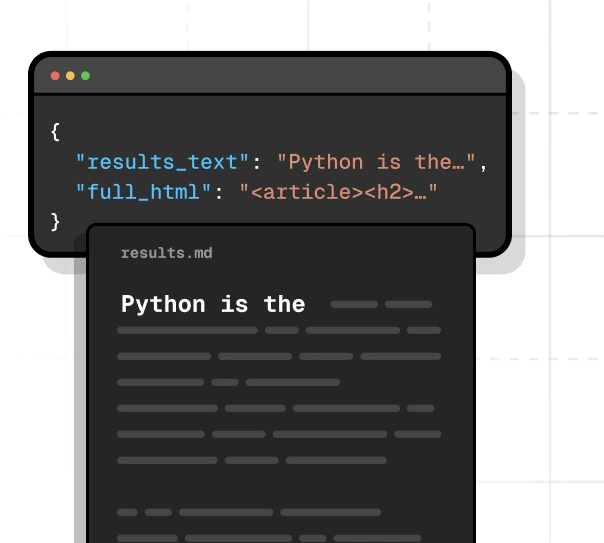
Extract the data you need
Retrieve rendered HTML, return page content as Markdown or text, define extraction rules for structured JSON, or use AI extraction to identify the required fields.
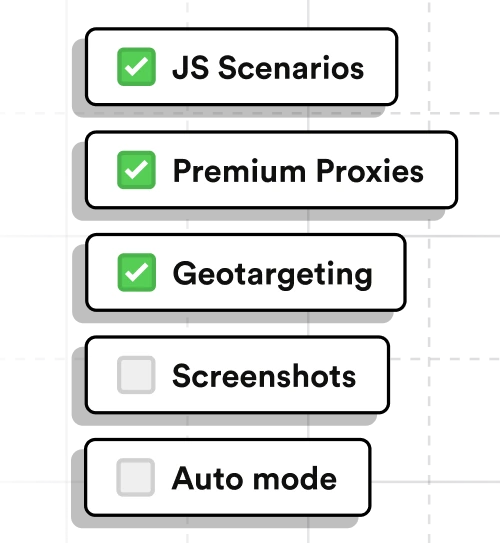
Customize and scale
Add JavaScript scenarios, premium or stealth proxies, geotargeting, screenshots, custom headers, sessions, and Auto Mode as your scraping requirements grow.
Our solution
A direct API for web scraping and extraction
ScrapingBee gives teams evaluating an Apify alternative a straightforward way to access, render, and extract web data without building workflows around hosted Actors, proxy infrastructure, or browser management.
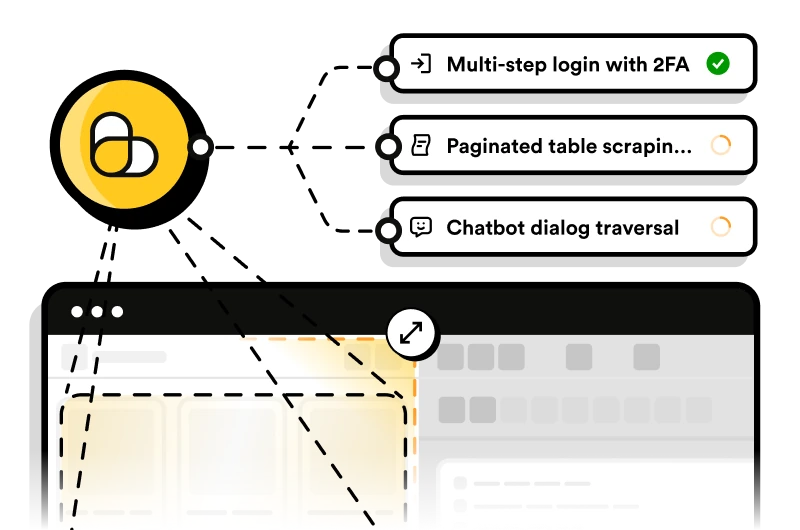
Handle dynamic and difficult websites
Render JavaScript, rotate premium or stealth proxies, run browser actions, retry failed requests, or use Auto Mode to automatically find a working configuration.
Explore the HTML API documentation
Extract data in the format you need
Return HTML, Markdown, text, screenshots, or structured JSON. Define extraction rules with CSS or XPath selectors, or use AI extraction when page structures vary.
Explore data extraction
Use dedicated APIs for common targets
Access purpose-built APIs for Google, Amazon, Walmart, YouTube, ChatGPT, Gemini, and other platforms when your workflow needs more than general-purpose page scraping.
Explore ScrapingBee APIsSwitching from Apify to ScrapingBee
Move from Actor-based workflows to direct API requests
ScrapingBee is not a drop-in replacement for Apify Actors. Instead, it provides a standard HTTP API for accessing, rendering, and extracting web pages, which can fit directly into existing application or data-pipeline code.
Keep your existing HTTP stack
Send requests with your current HTTP client and API authentication flow. ScrapingBee works with standard HTTP requests and does not require a dedicated SDK or runtime.
Replace platform-specific scraping steps gradually
Start by moving individual scraping tasks to ScrapingBee while keeping the rest of your pipeline unchanged. Scheduling, storage, queues, and other orchestration can remain in your existing infrastructure.
Add browser and proxy controls when needed
Enable JavaScript rendering, geotargeting, premium or stealth proxies, browser actions, and custom JavaScript for more difficult targets.
Extend the workflow as requirements grow
Add Auto Mode, AI extraction, Markdown or structured JSON output, screenshots, and dedicated APIs for platforms such as Google, Amazon, Walmart, YouTube, ChatGPT, and Gemini.
Build your own scraping stack or use ScrapingBee
If you're comparing Apify alternatives, one option is to assemble and operate your own scraping infrastructure. ScrapingBee handles much of that work through a single API, so your team can focus on the data pipeline rather than proxies, browsers, retries, and extraction infrastructure.
Initial setup

Build and maintain proxies, browsers, retries, and request logic

Send the target URL through one API
JavaScript rendering
Run and scale your own headless browsers
Enable browser rendering with a request parameter
Blocked requests
Diagnose failures and adjust proxies or browser settings
Use premium or stealth proxies, retries, or Auto Mode
Data extraction
Parse and clean page content in your own pipeline
Return HTML, Markdown, text, or structured JSON
Geotargeting
Source and manage proxies for each target country
Select a country with a two-letter code
Scaling
Scale browser, proxy, and retry infrastructure yourself
Increase concurrency through the same API
Developer experience
Documentation, tools, and support for your scraping workflow
When comparing Apify alternatives, integration effort matters alongside scraping features. ScrapingBee provides API documentation, working code examples, developer tools, integrations, and support for building and troubleshooting web scraping workflows.
API documentation
Find request parameters, response formats, authentication details, working examples, and a Postman collection covering ScrapingBee APIs.
Code examples and CLI
Start with examples for common programming languages and HTTP clients, or use the ScrapingBee CLI for scraping and extraction from the command line.
AI and automation integrations
Connect ScrapingBee through Remote MCP, LangChain, n8n, Make, Zapier, and other integrations when scraped data needs to feed agents, automations, or applications.
Engineer-led support
Contact the ScrapingBee team through live chat or email when you need help configuring requests or troubleshooting scraping workflows.
Why choose ScrapingBee for web scraping?
For teams evaluating Apify alternatives, ScrapingBee provides a direct API for accessing, rendering, and extracting web pages without maintaining proxy pools or browser infrastructure.
Managed proxy and browser infrastructure
ScrapingBee handles proxy rotation, JavaScript rendering, retries, and browser configuration so you can focus on collecting and processing web data.
Flexible extraction and output
Retrieve HTML, Markdown, text, screenshots, or structured JSON. Use CSS or XPath rules, natural-language queries, or AI extraction when you need specific fields.
Built for growing workloads
Run requests in parallel with plan-based concurrency, add premium or stealth proxies for more difficult targets, and use Auto Mode to find a working configuration automatically.
GDPR and CCPA compliant
ScrapingBee does not collect or store personal data from scraped websites unless you explicitly request it as part of your scraping workflow.
Web scraping plans built for scale
Choose a plan based on the number of API credits and concurrent requests your workflow needs. Upgrade, downgrade, or cancel at any time.
Need more credits or higher concurrency?
Want to compare ScrapingBee with Apify on your own workload?
"A reliable scraping backbone for multilingual market analysis."
"ScrapingBee really grew on us! Very good so far and we'll continue using it for a large project coming up as it just provides the consistency we need."
ScrapingBee has filled the void and allowed me to use an API to scrape instead of learning other libraries. "It has helped speed up our route towards complete competitive intelligence.
Trusted by more than 4,500 customers
ScrapingBee helps teams collect and extract web data without maintaining their own proxy, browser, and scraping infrastructure.


Test an Apify alternative
on your own workflow
Get 1,000 free API credits and see how ScrapingBee handles the websites, pages, and scraping workflows that matter to you.
Frequently asked questions
ScrapingBee can be a good Apify alternative when you want managed web scraping infrastructure without building your workflow around hosted Actors and Apify's storage and orchestration layer.
ScrapingBee focuses on web scraping through an HTTP API, with managed proxies, JavaScript rendering, browser actions, geotargeting, screenshots, and data extraction.
Apify is a broader cloud platform built around Actors: serverless programs that can scrape websites, automate browsers, process data, run on schedules, and store results in datasets, key-value stores, and request queues.
ScrapingBee differs from Apify mainly in its workflow model: ScrapingBee is an API-first web scraping service, while Apify is a broader Actor-based development and automation platform.
With ScrapingBee, you send a URL and configure how the page should be accessed, rendered, and extracted. With Apify, you can build your own Actors, run Actors from the Apify Store, schedule jobs, persist data, manage request queues, and combine Actors into larger workflows.
ScrapingBee may fit teams that want a direct scraping API, while Apify may fit workflows that benefit from hosted scraper code, persistent storage, scheduling, or the Actor marketplace.
If you are comparing cheaper alternatives to Apify, compare the cost of your actual scraping workload rather than headline subscription prices alone.
ScrapingBee uses monthly API credits, with requests consuming 1–75 credits depending on configuration. A classic-proxy request with JavaScript rendering disabled costs one credit, while the default JavaScript-rendered request costs five.
Apify charges for platform usage such as compute, proxies, data transfer, and storage. Actors in the Apify Store may also use different pricing models, so the total cost depends on which Actor you run and the resources or events involved.
Because the two platforms use different pricing models, there is no universal price-per-request comparison that applies to every workload.
ScrapingBee is a free Apify alternative to test, with 1,000 API credits for new accounts and no credit card required.
The free ScrapingBee credits are a signup allowance rather than an ongoing monthly free plan. Apify currently offers a recurring Free plan with $5 of platform usage each month, so teams looking for a free Apify alternative should distinguish between free trials and permanent free tiers.
Yes. ScrapingBee is suitable for large-scale and enterprise web scraping, with millions of monthly API credits, plan-based concurrency, and custom plans for larger workloads.
Its public plans scale to 8 million monthly API credits and 400 concurrent requests on Business+, while custom options are available when teams need more capacity. Enterprise requirements may also include geotargeting, browser rendering, extraction methods, support, and proxy configuration.
Yes. ScrapingBee provides an Apify MCP alternative for AI agents and automation workflows that need direct access to web scraping and extraction tools.
ScrapingBee's Remote MCP server supports capabilities including page scraping, structured extraction, screenshots, search, and dedicated APIs. Apify's MCP integration is more closely tied to its Actor ecosystem, including discovering and running Actors and accessing their results.
Yes. You can switch from Apify to ScrapingBee for web scraping tasks, although ScrapingBee is not a drop-in replacement for Apify Actors.
Scraping tasks that already work with known URLs can usually be moved to ScrapingBee through standard HTTP requests. Apify-specific features such as Actor schedules, datasets, request queues, and platform orchestration do not map directly to ScrapingBee and may need to remain in your existing infrastructure.
The best Apify alternative for web scraping depends on whether you need a direct scraping API or a broader hosted automation platform.
ScrapingBee is a strong option when you need managed proxies, JavaScript rendering, geotargeting, browser actions, AI extraction, and dedicated APIs through standard HTTP requests. Apify may be a better fit when your workflow depends on custom hosted Actors, scheduling, persistent platform storage, request queues, or its Actor marketplace.
Notice Regarding Third-Party Specifications & Trademarks: All feature comparisons, pricing details, and technical specifications concerning Apify, including Actors, browser automation, proxy services, storage, scheduling, API capabilities, and usage limits, are based on publicly available documentation accessible as of September 2026. Product specifications and features are subject to change by their respective owners over time.
Apify is a trademark of its respective owner.
ScrapingBee and Apify are separate, independent companies with no corporate relationship, common ownership, partnership, or other affiliation between them. ScrapingBee is not affiliated with, endorsed by, or sponsored by Apify.
All third-party product names and trademarks referenced on this page remain the exclusive property of their respective owners and are used solely for identification purposes under nominative fair use, to describe and compare publicly available product capabilities.
Purpose and Accuracy Statement: This comparison is intended to provide an objective, factual overview of publicly documented product capabilities to help readers evaluate available options. It is not intended to disparage, discredit, or misrepresent Apify or its products in any way. We recognise Apify as a capable web scraping and automation platform serving its own use cases, and we encourage readers to consult Apify's official website for the most current information.
Comparisons reflect publicly available information as of September 2026 and are made in good faith. If you believe any statement on this page is inaccurate or outdated, please contact us at contact@scrapingbee.com and we will review and correct it promptly.